Training catalogue

8 trainings

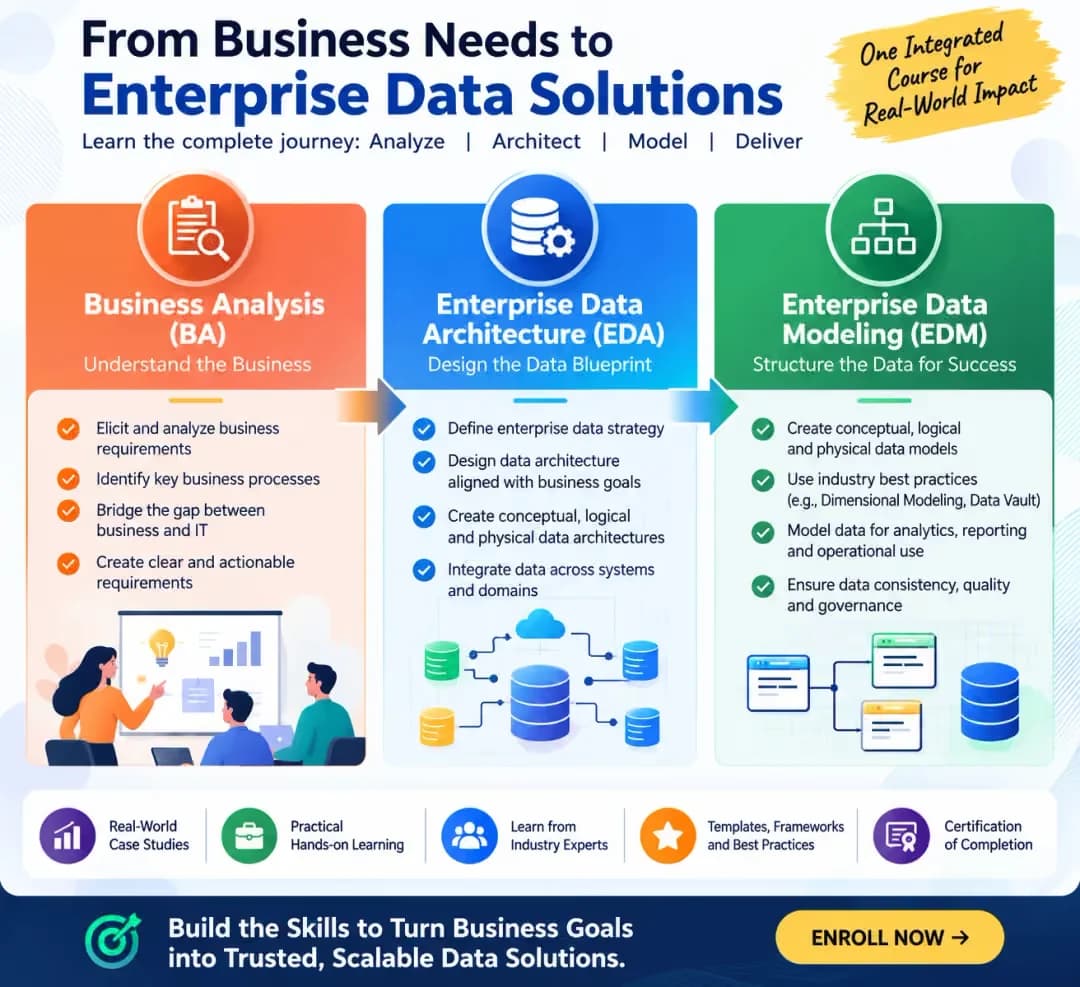
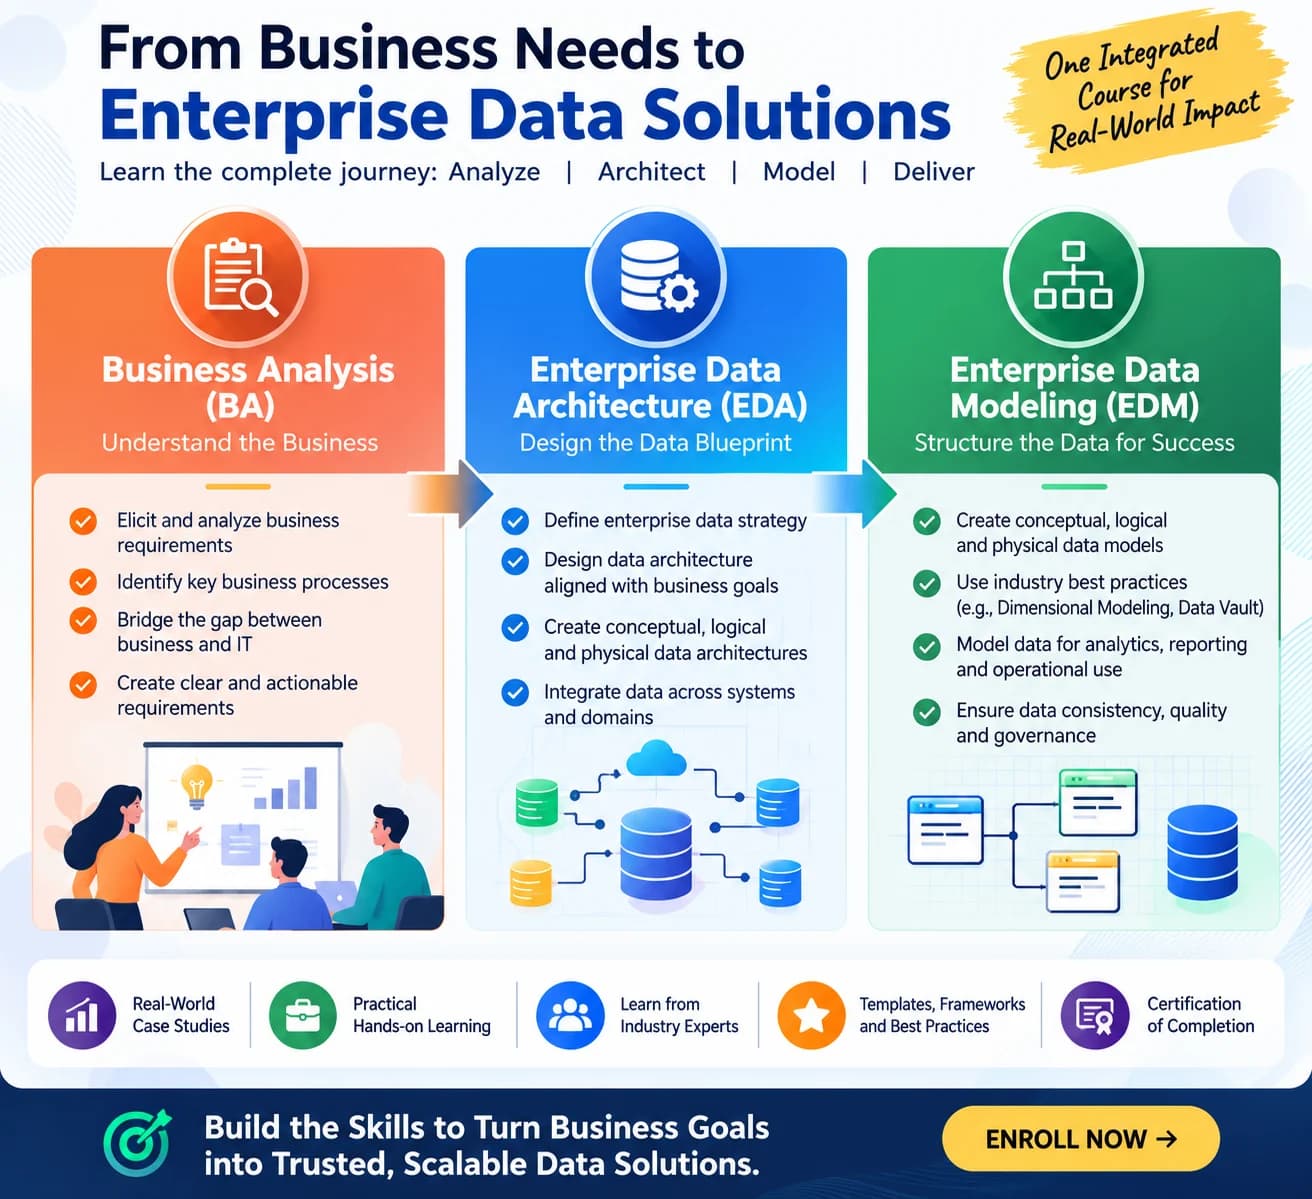
BA -> EDA -> EDM
Enterprise Data ArchitectureAdvanced

Business Requirement to Enterprise Data Architecture

Enables experienced data engineers to solve multiple business problems of different roles like: Business Analyst (Requirement Gathering) | Data Architecture (Design Data Layers), | Data Modeler (Design Data Structures)

with the help of AI as the core executor.

Duration
32 hrs
Mode
Live online
Starts
14 Nov 2026
Syllabus · 8 modules · Sat-Sun | 7 to 9 pm
  1. Business Requirements & Analysis · 3h
    • Introduction to enterprise data architecture

    • Business requirements versus functional and non-functional requirements

    • Role of the Business Analyst, Data Architect, Data Modeler and Data Engineer

    • Relationship between business architecture, application architecture and data architecture

    • Challenges in translating business language into technical solutions

    • Requirement gathering techniques

    • Business requirement documents (BRDs)

    • Functional and non-functional requirements

    • Business process identification

    • Business scenarios, use cases and user stories

    • Requirement classification and prioritization

    • Requirement ambiguity, duplication, inconsistency and gaps

    • Business events and their lifecycle

    • Business rules and decision points

    • Operational versus analytical requirements

  2. Business-to-Data Requirements · 3h
    • Business domains and subdomains

    • Data domain ownership

    • Master, reference, transactional and event data

    • Cross-domain data dependencies

    • Translating business activities into data requirements

    • Business objects versus data entities

    • Identifying data capture, update, retrieval and reporting requirements

    • Data attributes and business definitions

    • Data ownership and authoritative sources

    • Data retention and historical requirements

    • Operational, analytical and regulatory data needs

    • Source system identification

    • Source-to-business data mapping

    • Structured, semi-structured and unstructured data

    • Data profiling and source data assessment

    • Identifying missing, duplicate and conflicting data

    • Source system assessment and gap analysis

  3. Enterprise Data Architecture Fundamentals · 3h
    • What is enterprise data architecture?

    • Data architecture principles and standards

    • Centralized, decentralized and federated architectures

    • Enterprise data architecture building blocks

    • Data architecture patterns

    • Data architecture artifacts and documentation

    • Landing and staging layers

    • Bronze, Silver and Gold architecture

    • Enterprise Data Warehouse architecture

    • Operational Data Store (ODS)

    • Data Lake and Lakehouse

    • Data marts and semantic layers

    • Batch versus streaming architecture

    • Data integration patterns

    • ETL versus ELT

    • API-based and event-driven integration

    • Data replication and CDC

    • Data transformation and enrichment

    • Error handling and recovery

    • Data latency and integration SLAs

  4. Conceptual and Logical Data Modeling · 3h
    • Purpose of conceptual data models

    • Identifying business entities

    • Business entity relationships

    • Relationship types and cardinality

    • Enterprise conceptual data modeling

    • Logical data modeling methodology

    • Entities, attributes and relationships

    • Primary keys, alternate keys and candidate keys

    • Foreign keys and referential integrity

    • Identifying, non-identifying and recursive relationships

    • Associative entities and many-to-many relationships

    • Normalization: 1NF, 2NF and 3NF

    • Enterprise-wide entity reuse

    • Common business entities and shared data structures

    • Master data and reference data modeling

    • Transaction, event and status modeling

    • Effective dating and historical attributes

    • Address, contact and party modeling

    • Hierarchies and recursive relationships

    • Modeling complex business relationships

    • Model validation and quality checks

    • Logical model review and stakeholder approval

  5. Enterprise Data Modeling Approaches · 3h
    • Introduction to dimensional modeling and Kimball methodology

    • Star schema and snowflake schema

    • Fact tables and dimension tables

    • Identifying business processes and fact table grain

    • Transaction, periodic snapshot and accumulating snapshot facts

    • Conformed dimensions

    • Role-playing, junk and degenerate dimensions

    • Slowly Changing Dimensions (SCD Types 0, 1, 2 and 3)

    • Introduction to Data Vault 2.0 architecture

    • Business Vault versus Raw Vault

    • Hub, Link and Satellite structures

    • Business keys and hash keys

    • Satellite historization and load tracking

    • Effectivity and record tracking satellites

    • Multi-active satellites

    • Point-in-Time (PIT) and Bridge tables

    • Enterprise data warehouse integration patterns

    • Data Vault to dimensional data mart transformation

    • Hybrid enterprise data architecture

  6. Physical Architecture and Data Platform Design · 3h
    • Logical versus physical data models

    • Mapping logical entities to physical tables

    • Indexing and partitioning strategies

    • Denormalization and performance considerations

    • Database-specific implementation considerations

    • Forward and reverse engineering using ER/Studio

    • Data warehouse, data lake and Lakehouse architecture

    • Cloud data platform design considerations

    • Cloud storage and compute separation

    • Data ingestion and transformation services

    • Data platform scalability and elasticity

    • Platform selection based on business and technical requirements

    • Batch and streaming processing architecture

    • Data storage design and lifecycle

    • Data partitioning and clustering

    • CDC and historical data management

    • Data transformation architecture

    • Query performance and workload optimization

    • Data retention and archival

    • Technical architecture decisions and trade-offs

  7. Data Governance, Integration and Lineage · 3h
    • Data governance framework

    • Data ownership and stewardship

    • Data governance operating model

    • Business glossary and data dictionary

    • Technical and business metadata

    • Master data management (MDM)

    • Reference data management

    • Data classification and sensitive data identification

    • Data quality rules and validation

    • Data profiling and reconciliation

    • Data privacy and security principles

    • Role-based and attribute-based access control

    • Data masking and encryption

    • Personally identifiable information (PII) classification

    • Data retention and deletion requirements

    • Regulatory and audit requirements

    • Source-to-target mapping (STTM)

    • Transformation rules and derivation logic

    • Data lineage: source to report

    • Data reconciliation and auditability

    • ETL/ELT specifications

    • Documentation and traceability

  8. AI-Assisted Architecture and Capstone Project · 3h
    • Introduction to AI-assisted data architecture

    • AI-assisted BRD analysis and requirement extraction

    • Prompt engineering for business requirement analysis

    • Identifying entities, attributes and relationships using AI

    • Generating business rule catalogues

    • AI-assisted conceptual and logical model generation

    • AI-assisted source-to-target mapping

    • Analyze the business requirements and processes.

    • Identify business domains, entities and business rules.

    • Design the enterprise data architecture.

    • Develop a Data Vault and dimensional model for selected processes.

    • Prepare data flows, STTM and lineage.

    • Prepare the implementation blueprint.

    • Enterprise architecture walkthrough

    • Conceptual and logical model review

    • Data integration and modeling strategy review

    • Architecture decision documentation

    • Capstone project presentation

    • Final assessment and course completion

You will be able to:
  • Business Requirement Analysis.

  • Business-to-Data Mapping.

  • Enterprise Data Architecture Design.

  • Enterprise Data Modeling.

  • Dimensional Modeling.

  • Data Vault 2.0 Modeling.

  • Cloud Data Platform Architecture.

  • Data Integration and Lineage.

  • Data Governance and Quality.

  • AI-Assisted Data Architecture.

  • Architecture Documentation.

  • End-to-End Architecture Delivery.

₹18,435₹24,580per participant, + GST
Early Bird Offer · 25% off · till 16 Nov 2026
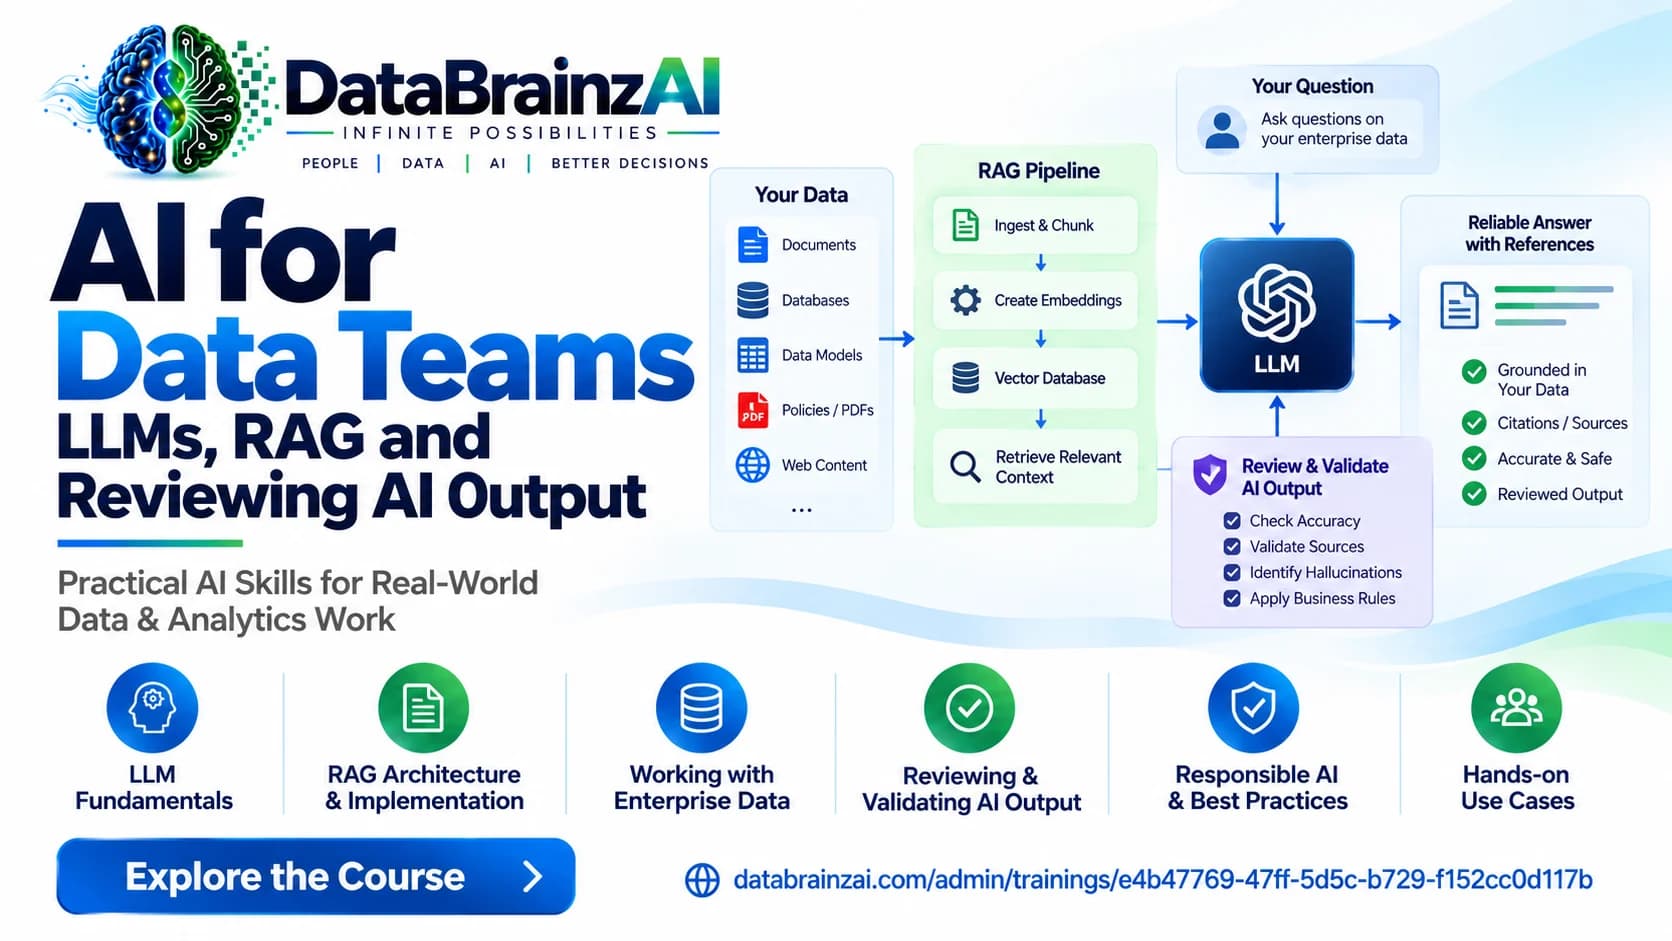
AI for Data Teams: LLMs, RAG and Reviewing AI Output
Artificial IntelligenceIntermediate

AI for Data Teams: LLMs, RAG and Reviewing AI Output

Use Generative AI effectively in data engineering | modeling | analytics and documentation | Explore LLMs | prompt engineering | RAG | vector search and responsible AI practices | Build prompts for SQL generation and data quality rules | Develop RAG pipeline using metadata.

Duration
16 hrs
Mode
Live online
Starts
20 Oct 2026
Syllabus · 4 modules · Sat–Sun, 10am–2pm IST
  1. LLM Basics for Data People · 3h
    • Introduction to Generative AI and LLMs

    • Traditional AI versus Generative AI

    • LLM architecture at a conceptual level

    • Tokens, tokenization and context windows

    • Training data, inference and next-token prediction

    • Model parameters and temperature

    • System prompts, user prompts and conversation context

    • Text generation and structured output

    • Strengths and limitations of LLMs

    • Hallucinations, outdated knowledge and ambiguous answers

    • Deterministic versus probabilistic outputs

    • Common use cases in data engineering, modeling and analytics

    • Overview of hosted and open-source LLMs

    • Responsible use of AI in enterprise environments

    • Ask an LLM to explain a complex SQL query.

    • Compare responses to the same prompt using different instructions.

    • Test how ambiguous business requirements affect generated answers.

    • Identify incorrect SQL and fabricated database objects in AI output.

  2. Prompting for Data Work · 4h
    • Prompt engineering fundamentals

    • Anatomy of a well-structured prompt

    • Role, task, context, constraints and output format

    • Zero-shot and few-shot prompting

    • Prompt templates and reusable prompt libraries

    • Structured outputs using JSON and tables

    • Prompting for SQL generation and explanation

    • Prompting for query debugging and optimization

    • Generating data dictionaries and technical documentation

    • Generating source-to-target mapping (STTM) drafts

    • Business requirement analysis and business rule extraction

    • AI-assisted entity and attribute identification

    • Iterative prompt refinement

    • Common prompt failure patterns

    • Generate SQL from a business question.

    • Generate table and column descriptions from database metadata.

    • Convert a business requirement into candidate entities and relationships.

    • Generate data quality rules from sample data.

  3. Retrieval and Vector Search · 4h
    • Limitations of LLMs when answering enterprise-specific questions

    • Introduction to Retrieval-Augmented Generation

    • RAG architecture and components

    • Document ingestion and preprocessing

    • Text extraction and cleaning

    • Chunking strategies and chunk size

    • Vector databases and vector indexes

    • Top-K retrieval

    • Metadata filtering

    • Context construction and prompt augmentation

    • RAG response generation

    • Basic RAG evaluation

    • Retrieval failures and incomplete context

    • Split documents into chunks.

    • Generate embeddings using an available embedding model.

    • Store and retrieve embeddings using a vector store.

    • Build a simple question-answering pipeline over metadata.

    • Compare ordinary LLM answers with RAG-grounded answers.

  4. Safe use and review · 5h
    • Responsible AI in data teams

    • Data privacy and confidentiality

    • Personally identifiable information (PII)

    • Sensitive data and enterprise data policies

    • Risks of sharing proprietary metadata

    • Safe use of public versus enterprise AI tools

    • Access control and data minimization

    • Prompt injection and untrusted retrieved content

    • Reviewing AI-generated SQL

    • Reviewing AI-generated data models and documentation

    • SQL execution, testing and reconciliation

    • Hallucination detection and factual verification

    • AI governance and auditability

    • Limitations of automated evaluation

    • Capstone project presentation and trainer review

    • Review an AI-generated SQL query and identify errors.

    • Identify sensitive information in sample prompts.

    • Evaluate RAG answers for relevance, correctness and source support.

    • Design a human approval workflow for AI-generated data artifacts.

You will be able to:
  • Explain how LLMs work, including tokens, context windows, embeddings and model limitations.

  • Identify hallucinations and other common failure modes in AI-generated content.

  • Design structured prompts for SQL generation, data documentation and data quality tasks.

  • Use AI to generate and review SQL queries, transformation logic and source-to-target mapping drafts.

  • Create prompts that support business requirement analysis and data modeling.

  • Explain embeddings, chunking, vector databases and semantic search.

  • Build a basic RAG pipeline over metadata and technical documentation.

  • Retrieve relevant information and generate context-grounded responses.

  • Evaluate AI-generated SQL, documentation and metadata using systematic review checklists.

  • Identify sensitive information and apply appropriate data protection practices.

  • Establish human review gates for AI-assisted data development.

  • Deliver a practical AI-assisted data project with documented testing and validation.

₹21,999per participant, + GST
Business Requirement to Enterprise Data Architecture
Enterprise Data ArchitectureAdvanced

Business Requirement to Enterprise Data Architecture

Enables experienced data engineers to solve multiple business problems of different roles like: Business Analyst (Requirement Gathering) | Data Architecture (Design Data Layers), | Data Modeler (Design Data Structures) with the help of AI as the core executor.

Duration
24 hrs
Mode
Live online
Starts
10 Nov 2026
Syllabus · 8 modules
  1. Business Requirements & Analysis · 2.5h
    • Introduction to enterprise data architecture

    • Business requirements versus functional and non-functional requirements

    • Role of the Business Analyst, Data Architect, Data Modeler and Data Engineer

    • Relationship between business architecture, application architecture and data architecture

    • Challenges in translating business language into technical solutions

    • Requirement gathering techniques

    • Business requirement documents (BRDs)

    • Functional and non-functional requirements

    • Business process identification

    • Business scenarios, use cases and user stories

    • Requirement classification and prioritization

    • Requirement ambiguity, duplication, inconsistency and gaps

    • Business events and their lifecycle

    • Business rules and decision points

    • Operational versus analytical requirements

  2. Business-to-Data Requirements · 3h
    • Business domains and subdomains

    • Data domain ownership

    • Master, reference, transactional and event data

    • Cross-domain data dependencies

    • Translating business activities into data requirements

    • Business objects versus data entities

    • Identifying data capture, update, retrieval and reporting requirements

    • Data attributes and business definitions

    • Data ownership and authoritative sources

    • Data retention and historical requirements

    • Operational, analytical and regulatory data needs

    • Source system identification

    • Source-to-business data mapping

    • Structured, semi-structured and unstructured data

    • Data profiling and source data assessment

    • Identifying missing, duplicate and conflicting data

    • Source system assessment and gap analysis

  3. Enterprise Data Architecture Fundamentals · 3h
    • What is enterprise data architecture?

    • Data architecture principles and standards

    • Centralized, decentralized and federated architectures

    • Enterprise data architecture building blocks

    • Data architecture patterns

    • Data architecture artifacts and documentation

    • Landing and staging layers

    • Bronze, Silver and Gold architecture

    • Enterprise Data Warehouse architecture

    • Operational Data Store (ODS)

    • Data Lake and Lakehouse

    • Data marts and semantic layers

    • Batch versus streaming architecture

    • Data integration patterns

    • ETL versus ELT

    • API-based and event-driven integration

    • Data replication and CDC

    • Data transformation and enrichment

    • Error handling and recovery

    • Data latency and integration SLAs

  4. Conceptual and Logical Data Modeling · 3h
    • Purpose of conceptual data models

    • Identifying business entities

    • Business entity relationships

    • Relationship types and cardinality

    • Enterprise conceptual data modeling

    • Logical data modeling methodology

    • Entities, attributes and relationships

    • Primary keys, alternate keys and candidate keys

    • Foreign keys and referential integrity

    • Identifying, non-identifying and recursive relationships

    • Associative entities and many-to-many relationships

    • Normalization: 1NF, 2NF and 3NF

    • Enterprise-wide entity reuse

    • Common business entities and shared data structures

    • Master data and reference data modeling

    • Transaction, event and status modeling

    • Effective dating and historical attributes

    • Address, contact and party modeling

    • Hierarchies and recursive relationships

    • Modeling complex business relationships

    • Model validation and quality checks

    • Logical model review and stakeholder approval

  5. Enterprise Data Modeling Approaches · 3h
    • Introduction to dimensional modeling and Kimball methodology

    • Star schema and snowflake schema

    • Fact tables and dimension tables

    • Identifying business processes and fact table grain

    • Transaction, periodic snapshot and accumulating snapshot facts

    • Conformed dimensions

    • Role-playing, junk and degenerate dimensions

    • Slowly Changing Dimensions (SCD Types 0, 1, 2 and 3)

    • Introduction to Data Vault 2.0 architecture

    • Business Vault versus Raw Vault

    • Hub, Link and Satellite structures

    • Business keys and hash keys

    • Satellite historization and load tracking

    • Effectivity and record tracking satellites

    • Multi-active satellites

    • Point-in-Time (PIT) and Bridge tables

    • Enterprise data warehouse integration patterns

    • Data Vault to dimensional data mart transformation

    • Hybrid enterprise data architecture

  6. Physical Architecture and Data Platform Design · 3h
    • Logical versus physical data models

    • Mapping logical entities to physical tables

    • Indexing and partitioning strategies

    • Denormalization and performance considerations

    • Database-specific implementation considerations

    • Forward and reverse engineering using ER/Studio

    • Data warehouse, data lake and Lakehouse architecture

    • Cloud data platform design considerations

    • Cloud storage and compute separation

    • Data ingestion and transformation services

    • Data platform scalability and elasticity

    • Platform selection based on business and technical requirements

    • Batch and streaming processing architecture

    • Data storage design and lifecycle

    • Data partitioning and clustering

    • CDC and historical data management

    • Data transformation architecture

    • Query performance and workload optimization

    • Data retention and archival

    • Technical architecture decisions and trade-offs

  7. Data Governance, Integration and Lineage · 3h
    • Data governance framework

    • Data ownership and stewardship

    • Data governance operating model

    • Business glossary and data dictionary

    • Technical and business metadata

    • Master data management (MDM)

    • Reference data management

    • Data classification and sensitive data identification

    • Data quality rules and validation

    • Data profiling and reconciliation

    • Data privacy and security principles

    • Role-based and attribute-based access control

    • Data masking and encryption

    • Personally identifiable information (PII) classification

    • Data retention and deletion requirements

    • Regulatory and audit requirements

    • Source-to-target mapping (STTM)

    • Transformation rules and derivation logic

    • Data lineage: source to report

    • Data reconciliation and auditability

    • ETL/ELT specifications

    • Documentation and traceability

  8. AI-Assisted Architecture and Capstone Project · 3h
    • Introduction to AI-assisted data architecture

    • AI-assisted BRD analysis and requirement extraction

    • Prompt engineering for business requirement analysis

    • Identifying entities, attributes and relationships using AI

    • Generating business rule catalogues

    • AI-assisted conceptual and logical model generation

    • AI-assisted source-to-target mapping

    • Analyze the business requirements and processes.

    • Identify business domains, entities and business rules.

    • Design the enterprise data architecture.

    • Develop a Data Vault and dimensional model for selected processes.

    • Prepare data flows, STTM and lineage.

    • Prepare the implementation blueprint.

    • Enterprise architecture walkthrough

    • Conceptual and logical model review

    • Data integration and modeling strategy review

    • Architecture decision documentation

    • Capstone project presentation

    • Final assessment and course completion

You will be able to:
  • Business Requirement Analysis.

  • Business-to-Data Mapping.

  • Enterprise Data Architecture Design.

  • Enterprise Data Modeling.

  • Dimensional Modeling.

  • Data Vault 2.0 Modeling.

  • Cloud Data Platform Architecture.

  • Data Integration and Lineage.

  • Data Governance and Quality.

  • AI-Assisted Data Architecture.

  • Architecture Documentation.

  • End-to-End Architecture Delivery.

₹19,970per participant, + GST
Dimensional Modeling for Analytics: From Business Requirements to Star Schema
Dimensional ModelingIntermediate

Dimensional Modeling for Analytics: From Business Requirements to Star Schema

Design enterprise-ready dimensional data models, analytics, reporting, business intelligence. Course covers business process analysis, fact and dimension tables, grain definition, star and snowflake schemas, slowly changing dimensions, advanced dimensional modeling, and SQL implementation.

Duration
18 hrs
Mode
Live online
Starts
20 Oct 2026
Syllabus · 12 modules · Weekday evenings, 5–6:30pm IST
  1. Introduction to Data Warehousing and Dimensional Modeling · 2h

    OBJECTIVE:

    • Understand the role of dimensional modeling in modern analytical data platforms

    TOPICS:

    • oltp vs. olap systems

    • operational databases vs. analytical databases

    • enterprise data warehouse

    • data mart and lakehouse

    • Introduction to the Kimball methodology

    • Dimensional modeling vs. normalized modeling

    • Star schema vs. snowflake schema

    • Analytical workloads and reporting requirements

    • Overview of modern data warehouse architecture

    PRACTICAL ACTIVITY:

    • Examine an operational order-processing database and identify the information required for analytical reporting

    ASSESSMENT:

    • Identify the differences between an operational model and an analytical model.

  2. Business Process Analysis and Dimensional Design · 2h

    OBJECTIVE:

    • convert business requirements into a dimensional modeling design.

    TOPICS:

    • business process identification

    • business requirements and analytical questions

    • identifying business events and measures

    • identifying dimensions and descriptive attributes

    • business process matrix

    • dimensional bus architecture

    • identifying shared dimensions

    • translating business requirements into facts and dimensions

    PRACTICAL ACTIVITY:

    • analyze a retail business case and prepare a business process matrix covering sales, returns, inventory and payments.

    ASSESSMENT:

    • create a preliminary dimensional design from a business requirements document.

  3. Fact Table Design and Grain Definition · 2h

    OBJECTIVE:

    • design fact tables with the appropriate grain

    • measures and dimensional relationships.

    TOPICS:

    • fact table fundamentals

    • defining and documenting fact table grain

    • transaction fact tables

    • periodic snapshot fact tables

    • accumulating snapshot fact tables

    • factless fact tables

    • additive, semi-additive and non-additive measures

    • foreign keys and dimensional relationships

    • multiple facts and different grains

    • common fact table design mistakes

    PRACTICAL ACTIVITY:

    • Design sales transaction, monthly inventory snapshot and order fulfillment fact tables.

    ASSESSMENT:

    • Document the grain and measures for three different business processes.

  4. Dimension Table Design · 2h

    OBJECTIVE:

    • design dimensions that provide consistent and meaningful analytical context.

    TOPICS:

    • dimension table fundamentals

    • surrogate keys vs. natural keys

    • dimension attributes and hierarchies

    • conformed dimensions

    • role-playing dimensions

    • degenerate dimensions

    • junk dimensions

    • mini-dimensions

    • date and time dimensions

    • handling unknown and not-applicable dimension members.

    PRACTICAL ACTIVITY:

    • design customer, product, date, location and sales-channel dimensions.

  5. Star Schema and Snowflake Schema Design · 2h

    OBJECTIVE:

    • Build complete dimensional schemas and evaluate alternative designs.

    TOPICS:

    • star schema architecture

    • snowflake schema architecture

    • fact-to-dimension relationships

    • one-to-many dimensional relationships

    • dimension normalization and denormalization

    • shared dimensions across business processes

    • multiple fact tables

    • multi-star and constellation schemas

    • schema design trade-offs

    • designing schemas for BI consumption.

    PRACTICAL ACTIVITY:

    • Convert a business requirements model into a star schema and compare it with a snowflake alternative.

    ASSESSMENT:

    • Produce a logical star schema diagram and justify its design decisions.

  6. Slowly Changing Dimensions (SCD) · 2h

    OBJECTIVE:

    • Implement historical tracking of changes in dimensional attributes.

    TOPICS:

    • why dimensional attributes change

    • SCD type 0: Retain original value

    • SCD type 1: overwrite

    • SCD type 2: historical versioning

    • SCD type 3: previous value

    • effective dates and expiration dates

    • current record indicators

    • surrogate key management

    • late-arriving dimension records

    • historical fact association

    • SQL implementation of SCD Type 1 and Type 2

    PRACTICAL ACTIVITY:

    • implement customer and product dimension changes using SQL.

    ASSESSMENT:

    • design an SCD Type 2 dimension and write SQL to process new and changed records.

  7. Advanced Dimensional Modeling Techniques · 2h

    OBJECTIVE:

    • address complex business requirements using advanced dimensional modeling patterns.

    TOPICS:

    • multiple fact tables with shared dimensions

    • header and line-level transaction facts

    • bridge tables for many-to-many relationships

    • multivalued dimensions

    • allocating measures across bridge relationships

    • hierarchical dimensions

    • ragged and variable-depth hierarchies

    • parent-child relationships

    • snapshot facts with changing dimensional relationships

    • handling multiple currencies and units of measure

    PRACTICAL ACTIVITY:

    • design a banking or investment model with customers, accounts, transactions and joint account holders.

    ASSESSMENT:

    • solve a many-to-many dimensional modeling scenario using a bridge table.

  8. Date, Time and Advanced Fact Modeling · 2h

    OBJECTIVE:

    • Model time-dependent business processes and complex measures.

    TOPICS:

    • date dimension design

    • multiple date roles in a fact table

    • business calendars and fiscal calendars

    • event-based and periodic measurements

    • accumulating snapshots and milestone dates

    • inventory and account balance snapshots

    • semi-additive balances

    • fact table partitioning considerations

    • late-arriving facts and dimensions

    • handling corrections and restatements

    PRACTICAL ACTIVITY:

    • model an order lifecycle with order, shipment, delivery and payment milestones.

    ASSESSMENT:

    • design an accumulating snapshot fact table and demonstrate its analytical use.

  9. Physical Dimensional Modeling and SQL Implementation · 2h

    OBJECTIVE:

    • Translate logical dimensional designs into implementable database structures.

    TOPICS:

    • logical vs. physical dimensional models

    • naming standards and data types

    • primary keys and foreign keys

    • creating fact and dimension tables using SQL

    • surrogate key generation

    • loading dimensions and facts

    • referential integrity and data quality

    • incremental loading concepts

    • SQL joins between fact and dimension tables

    • query patterns for analytical reporting.

    PRACTICAL ACTIVITY:

    • Implement a sales star schema using SQL and populate sample data.

    ASSESSMENT:

    • Create the physical schema and execute analytical queries against it.

  10. Dimensional Modeling for Modern Data Platforms · 2h

    OBJECTIVE:

    • Understand how dimensional models are implemented in modern cloud data platforms.

    TOPICS:

    • dimensional modeling in Snowflake

    • dimensional modeling in Azure and Microsoft Fabric

    • dimensional modeling in Databricks and Delta Lake

    • data warehouse vs. lakehouse implementation

    • data quality and reconciliation

    • performance considerations for analytical workloads

    • partitioning, clustering and indexing concepts

    • BI semantic models and dimensional relationships.

    PRACTICAL ACTIVITY:

    • review the implementation of a star schema in a cloud data warehouse and write analytical SQL queries.

    ASSESSMENT:

    • identify implementation considerations for deploying a dimensional model on a selected platform.

  11. Dimensional Model Validation and Optimization · 2h

    OBJECTIVE:

    • Validate dimensional models and improve their suitability for reporting and analytics.

    TOPICS:

    • reviewing the business process matrix

    • grain consistency and dimensional conformance

    • fact and dimension validation

    • referential integrity checks

    • handling duplicate and missing dimension members

    • aggregation correctness

    • query performance analysis

    • avoiding double counting

    • model usability for BI developers

    • common dimensional modeling anti-patterns.

    PRACTICAL ACTIVITY:

    • Review a deliberately flawed dimensional model, identify design issues and correct them.

    ASSESSMENT:

    • Complete a dimensional model review checklist and demonstrate the corrected design.

  12. End-to-End Dimensional Modeling Project · 2h

    OBJECTIVE:

    • Apply the complete dimensional modeling lifecycle to a realistic business scenario.

    TOPICS:

    • business requirements analysis

    • business process identification

    • fact grain definition

    • dimension and measure identification

    • star schema design

    • SCD strategy selection

    • physical model creation

    • analytical SQL and reporting validation

    • model documentation and presentation

    PRACTICAL ACTIVITY:

    • design a dimensional data warehouse for a retail, banking or logistics business case.

    FINAL ASSESSMENT:

    • submit and present a complete dimensional model, including business process matrix, schema diagram, table specifications and sample analytical queries.

You will be able to:
  • Analyze business requirements and identify analytical business processes.

  • Define the grain of a fact table and explain its impact on dimensional design.

  • Identify and design fact tables and dimension tables.

  • Build star schemas and understand when snowflake schemas may be appropriate.

  • Design transaction, periodic snapshot, and accumulating snapshot fact tables.

  • Implement slowly changing dimensions (Types 0, 1, 2 and 3).

  • Design conformed, role-playing, junk, degenerate, and other specialized dimensions.

  • Model complex business scenarios involving multiple fact tables and shared dimensions.

  • Translate dimensional designs into physical database tables using SQL.

  • Validate dimensional models against business requirements and analytical queries.

  • Recognize common dimensional modeling mistakes and improve model usability and maintainability.

  • Design an end-to-end dimensional model for a practical business case.

₹9,970per participant, + GST
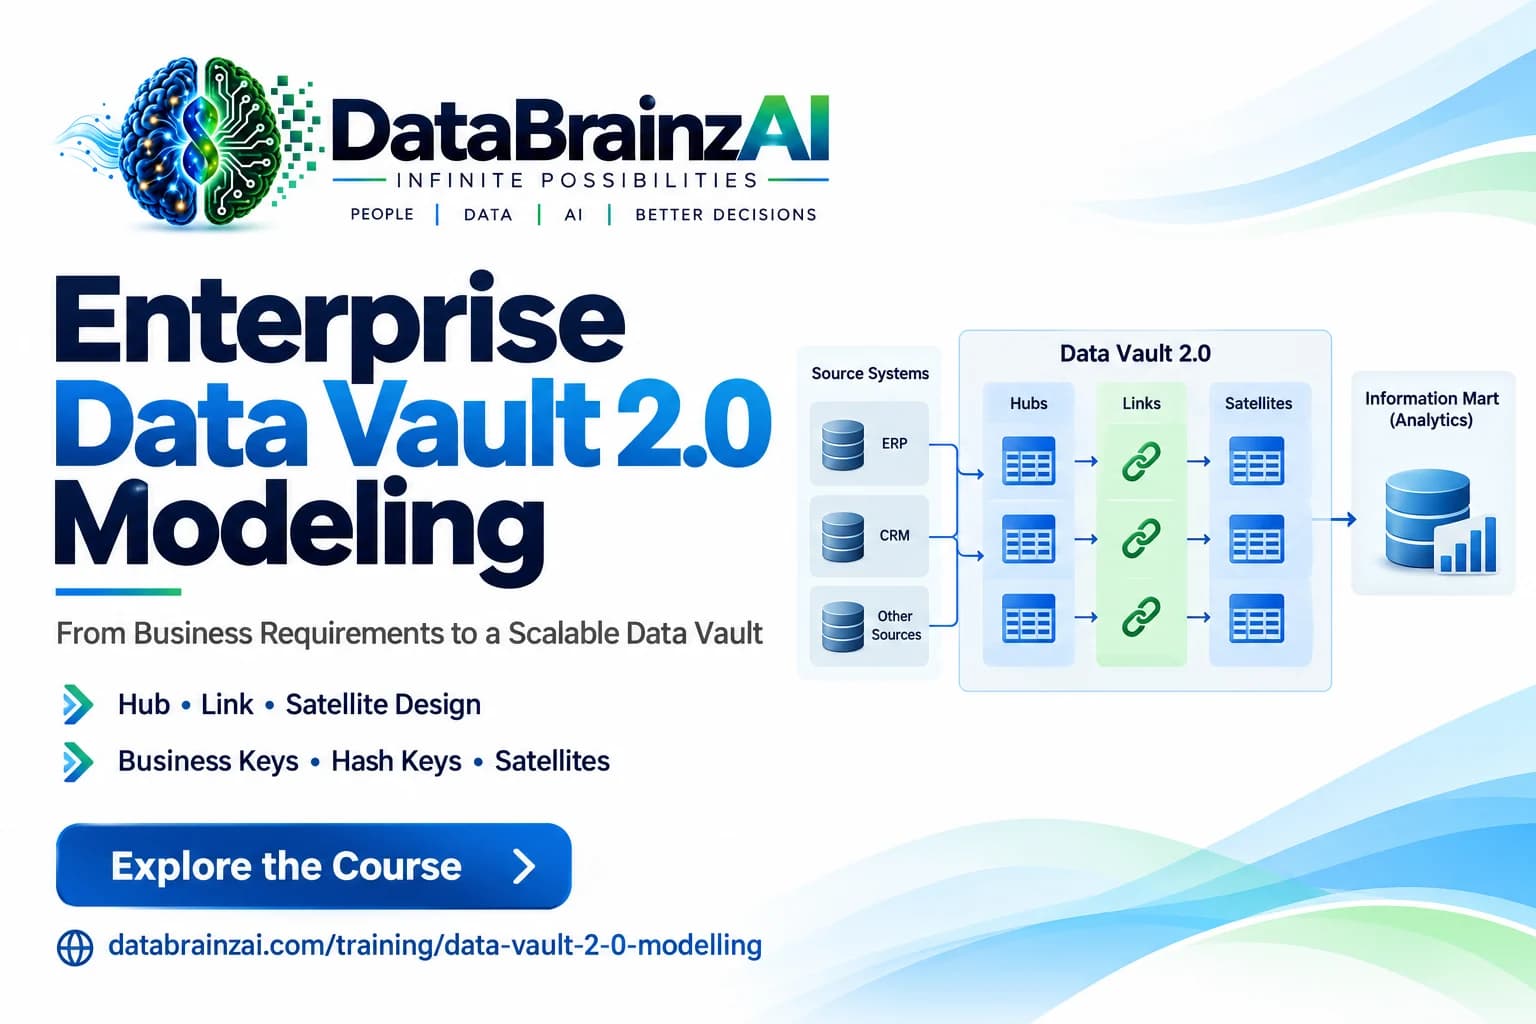
Enterprise Data Vault 2.0 Modeling
Data Vault 2.0Advanced

Enterprise Data Vault 2.0 Modeling

Design enterprise-grade data vault 2.0 models, from business requirements and source system analysis to raw vault, business vault and information marts. design hub, link and satellite, keys, historization, PIT tables, bridges and advanced modeling patterns. real business scenarios.

Duration
30 hrs
Mode
Live online
Starts
26 Oct 2026
Syllabus · 15 modules · Weekends, 10am–2pm IST
  1. Enterprise Data Vault 2.0 Architecture · 2h

    OBJECTIVE:

    • Understand the principles, components and architectural layers of Data Vault 2.0.

    TOPICS:

    • Evolution of enterprise data warehousing

    • Data Vault 1.0 versus Data Vault 2.0.

    • Data Vault 2.0 architecture and its three pillars: modeling, methodology and architecture

    • Raw Vault, Business Vault and Information Marts

    • Data Vault in modern cloud data platforms

    • Data integration, scalability, auditability and agility

    PRACTICAL EXCERCISES:

    • Design a high-level Data Vault architecture for a banking enterprise

    ASSESSMENT:

    • Identify the responsibilities of each architectural layer.

  2. Business Requirements and Source System Analysis · 2h

    OBJECTIVE:

    • Translate business requirements and source system structures into Data Vault modeling requirements

    TOPICS:

    • Business processes, business rules and business concepts

    • Identifying business entities and their relationships

    • Business keys versus technical keys

    • Source system profiling and metadata analysis

    • Identifying master, transactional, reference and event data

    • Source-to-business concept mapping

    • Identifying data integration challenges

    PRACTICAL EXCERCISES:

    • Analyze customer, account and transaction source systems and identify candidate Hubs, Links and Satellites

    ASSESSMENT:

    • Prepare a business-to-source mapping document.

  3. Data Vault 2.0 Modeling Fundamentals · 2h

    OBJECTIVE:

    • Understand the core modeling principles and establish enterprise modeling standards

    TOPICS:

    • Business keys and their stability

    • Hash keys and hash differences

    • Hub, Link and Satellite fundamentals

    • Insert-only modeling and historical preservation

    • Naming conventions and modeling standards

    • Logical versus physical Data Vault models

    • Standard metadata and audit columns

    PRACTICAL EXCERCISES:

    • Create a basic logical model for customer and account data.

    ASSESSMENT:

    • Review the model for correct business key and object classification.

  4. Enterprise Hub Modeling · 2h

    OBJECTIVE:

    • Design enterprise Hubs using business keys and integrate multiple source systems.

    TOPICS:

    • Hub identification and design principles

    • Business key selection and standardization

    • Composite and concatenated business keys

    • Enterprise versus source-specific business keys

    • Hub relationships and business domains

    • Hub integration across multiple source systems

    • Hub metadata and audit attributes

    • Handling missing and invalid business keys

    PRACTICAL EXCERCISES:

    • Design Customer, Account, Product, Employee and Transaction Hubs for a financial services organization.

    ASSESSMENT:

    • Evaluate Hub design against enterprise modeling standards.

  5. Enterprise Link Modeling · 2h

    OBJECTIVE:

    • Model relationships among enterprise business concepts using Links.

    TOPICS:

    • Link identification and design principles

    • Transactional and non-transactional Links

    • Standard, dependent-child and hierarchical relationships

    • Composite business relationships

    • Link cardinality and relationship constraints

    • Multi-source relationship integration

    • Link granularity and modeling decisions

    • Link naming and metadata standards

    PRACTICAL EXCERCISES:

    • Model customer-account, account-transaction, customer-product and employee-organization relationships.

    ASSESSMENT:
    - Validate Link grain, participating Hubs and business meaning.

  6. Enterprise Satellite Modeling · 2h

    OBJECTIVE:

    • Design Satellites for descriptive attributes, history and source-specific data.

    TOPICS:

    • Satellite identification and design

    • Hub Satellites and Link Satellites

    • Source-aligned and business-aligned Satellites

    • Satellite splitting and grouping strategies

    • Attribute historization and change tracking

    • HashDiff design and change detection

    • Load date, record source and audit attributes

    • Satellite granularity and naming standards

    PRACTICAL EXCERCISES:

    • Design customer profile, account status, transaction details and customer risk Satellites.

    ASSESSMENT:

    • Review Satellite separation, historization and attribute placement.

  7. Advanced Data Vault Modeling Patterns · 2h

    OBJECTIVE:

    • Apply advanced Data Vault structures to complex enterprise scenarios.

    • TOPICS: Multi-Active Satellites

    • Same-as Links and identity resolution

    • Hierarchical Links and recursive relationships

    • Non-Historized Links

    • Effectivity Satellites

    • Status tracking and relationship lifecycle

    • Dependent-child relationships

    • Choosing appropriate modeling patterns

    PRACTICAL EXCERCISES:

    • Model multiple customer addresses, account ownership changes, customer identity matching and organizational hierarchies.

    ASSESSMENT:

    • Select and justify modeling patterns for given business scenarios.

  8. Historical Data and Temporal Modeling · 2h

    OBJECTIVE:

    • Model historical changes, effective dates and temporal relationships.

    TOPICS:

    • Historical data preservation

    • Load time versus business effective time

    • Valid-time and transaction-time concepts

    • Late-arriving and out-of-order data

    • Retroactive corrections

    • Relationship effectivity

    • Handling deleted and deactivated records

    • Historical reconstruction and point-in-time analysis.

    PRACTICAL EXCERCISES:

    • Model customer address changes, account closures and backdated transaction corrections.

    ASSESSMENT:

    • Design a temporal model for a changing customer-account relationship.

  9. Raw Vault Architecture and Modeling · 2h

    OBJECTIVE:

    • Build an integrated Raw Vault model from heterogeneous source systems.

    TOPICS:

    • Raw Vault principles and design standards

    • Source-aligned modeling

    • Multi-source data integration

    • Raw Vault object dependencies

    • Load sequencing and dependency management

    • Data lineage and traceability

    • Record source and audit requirements.

    PRACTICAL EXCERCISES:

    • Build a Raw Vault model using customer and account data from multiple banking systems.

    ASSESSMENT:

    • Review the complete Raw Vault logical model and its source traceability.

  10. Business Vault Modeling · 2h

    OBJECTIVE:

    • Design Business Vault structures to implement reusable business rules and derived data.

    TOPICS:

    • Business Vault architecture and design principles

    • Raw versus derived business information

    • Business rules and transformation logic

    • Derived and computed Satellites

    • Business effectivity and calculated relationships

    • Business key resolution and survivorship

    • Rule versioning and historical recalculation

    • Reusable business logic.

    PRACTICAL EXCERCISES:

    • Design Business Vault objects for customer classification, account risk and consolidated customer identity.

    ASSESSMENT:

    • Classify business rules and map them to suitable Business Vault structures.

  11. PIT Tables and Bridge Tables · 2h

    OBJECTIVE:

    • Design PIT and Bridge structures to simplify point-in-time queries and complex relationship navigation.

    TOPICS:

    • Purpose and architecture of PIT tables

    • Snapshot, full-history, rolling and incremental PIT patterns

    • Satellite selection and effective record lookup

    • PIT refresh and maintenance strategies

    • Bridge table design and relationship traversal

    • Hierarchical and recursive Bridge tables

    • Performance and storage considerations

    • Virtual versus materialized access structures.

    PRACTICAL EXCERCISES:

    • Design a Customer PIT, Account PIT and customer-account Bridge for reporting requirements

    ASSESSMENT:

    • Select appropriate PIT and Bridge patterns for different query scenarios.

  12. Data Vault to Dimensional Modeling · 2h

    OBJECTIVE:

    • Transform integrated Data Vault structures into reporting-ready dimensional models.

    TOPICS:

    • Information Mart architecture

    • Data Vault versus dimensional modeling

    • Identifying fact table grain

    • Transaction, periodic snapshot and accumulating snapshot facts

    • Dimension design and surrogate keys

    • Slowly Changing Dimensions

    • Handling many-to-many relationships

    • Mapping Hubs, Links and Satellites to dimensions and facts

    • Historical and current-state reporting.

    PRACTICAL EXCERCISES:

    • Design a banking dimensional model for account balances, transactions and customer activity using the Data Vault as the source.

    ASSESSMENT:

    • Validate fact grain, dimension relationships and historical reporting requirements.

  13. Physical Data Vault Design and Implementation · 2h

    OBJECTIVE:

    • Convert logical Data Vault models into implementation-ready physical designs.

    TOPICS:

    • Logical-to-physical model transformation

    • Database-specific data types and naming standards

    • Primary keys, foreign keys and indexing strategies

    • Hash key and HashDiff implementation considerations

    • Partitioning and clustering strategies

    • Audit columns and technical metadata

    • Physical modeling in ER/Studio or ERwin | Platform-specific design considerations for Oracle, Snowflake and SQL Server

    PRACTICAL EXCERCISES:

    • Generate physical tables and DDL from selected logical Data Vault models.

    ASSESSMENT:

    • Review physical model consistency and implementation readiness.

  14. Enterprise Data Vault Modeling Standards and Governance · 2h

    OBJECTIVE:

    • Establish enterprise-wide modeling standards, quality controls and governance practices.

    TOPICS:

    • Enterprise modeling standards and reusable patterns

    • Model naming and documentation conventions

    • Business glossary and metadata management

    • Model versioning and change management

    • Source-to-target mapping and data lineage

    • PII classification and data protection metadata

    • Data quality rules and model validation

    • Model review checklists and design governance

    PRACTICAL EXCERCISES:

    • Create a modeling standards document and perform a peer review of an enterprise Data Vault model.

    ASSESSMENT:

    • Conduct a structured model quality review.

  15. Enterprise Data Vault Capstone Project · 2h

    OBJECTIVE:

    • Apply the course concepts to design a complete enterprise Data Vault solution.

    CASE STUDY:

    • Global Financial Services Data Warehouse

    PROJECT ACTIVITIES:

    • Analyze business requirements

    • Identify business keys, entities and relationships

    • Map source systems to enterprise business concepts

    • Design the Raw Vault with Hubs, Links and Satellites

    • Apply advanced modeling patterns

    • Design Business Vault structures

    • Design PIT and Bridge tables

    • Develop dimensional Information Marts

    • Prepare source-to-target mappings and data lineage

    • Create model documentation.

    DELIVERABLES:

    • Enterprise Data Vault architecture diagram

    • Business process and source mapping

    • Complete logical Data Vault model

    FINAL ASSESSMENT:

    • Present and defend the enterprise model, explain key design decisions and respond to a technical model review.

You will be able to:
  • Analyze complex business requirements and translate them into enterprise Data Vault 2.0 models.

  • Identify business keys, define business concepts and design Hubs, Links and Satellites.

  • Design Raw Vault architectures that integrate data from multiple source systems.

  • Apply appropriate historization, change tracking and auditability strategies.

  • Model complex relationships, including many-to-many relationships, hierarchies and recursive relationships.

  • Design advanced Data Vault structures, including Multi-Active Satellites, Same-as Links, PIT tables and Bridge tables.

  • Distinguish between Raw Vault, Business Vault and Information Mart responsibilities.

  • Design Business Vault structures using derived data, business rules and calculated attributes.

  • Develop source-to-target mappings and define data lineage and load dependencies.

  • Design dimensional Information Marts using Data Vault as the underlying integration layer.

  • Evaluate modeling alternatives for scalability, flexibility, performance and maintainability.

  • Produce a complete enterprise Data Vault 2.0 logical model and its supporting design documentation.

₹13,587₹15,985per participant, + GST
Early Bird Offer · 15% off
Power BI: Advanced Data Modeling, DAX, Service & Administration
Power BIIntermediate

Power BI: Advanced Data Modeling, DAX, Service & Administration

Take your Power BI skills to the next level with hands-on training in advanced data modeling | DAX | interactive dashboards | deployment and Power BI Administration | Learn to develop | optimize | secure and manage enterprise-level BI solutions.

Duration
30 hrs
Mode
Live online
Starts
15 Oct 2026
Syllabus · 9 modules · Sat–Sun, 10am–1pm IST
  1. Power BI Architecture & Data Connectivity · 2h
    • Power BI Desktop, Power BI Service and Power BI Mobile

    • Power BI architecture and data flow

    • Import, DirectQuery and Live Connection

    • Composite models and Direct Lake overview

    • Connecting to SQL Server, Excel, CSV and Snowflake

    • Data source credentials and connection management

  2. Advanced Power Query · 3h
    • Advanced transformations and data cleansing

    • Merge and Append queries

    • Group By and Pivot/Unpivot

    • Parameters and dynamic data sources

    • Custom columns and conditional logic

    • M language fundamentals

    • Query folding and performance optimization

    • Error handling and data profiling

  3. Advanced Data Modeling · 4h
    • Star schema design and dimensional modeling

    • Fact and dimension tables

    • Defining grain and relationships

    • Active and inactive relationships

    • One-to-many and many-to-many relationships

    • Role-playing dimensions

    • Date dimension and multiple date relationships

    • Handling slowly changing dimensions

    • Bidirectional filtering and its implications

    • Model optimization and reducing cardinality

  4. DAX Fundamentals to Advanced DAX · 5h
    • Calculated columns, calculated tables and measures

    • Row context and filter context

    • CALCULATE and filter modifiers

    • ALL, ALLEXCEPT, REMOVEFILTERS and KEEPFILTERS

    • RELATED, RELATEDTABLE and LOOKUPVALUE

    • Iterators: SUMX, AVERAGEX and COUNTX

    • Variables using VAR and RETURN

    • Time intelligence

    • YTD, QTD, MTD and previous-period calculations

    • Ranking, percentage contribution and running totals

    • Dynamic measures and calculation groups overview

    • DAX performance and optimization

  5. Advanced Visualization & Reporting · 3h
    • Advanced charts and custom visuals

    • Drill-down and drill-through

    • Bookmarks and buttons

    • Dynamic titles and conditional formatting

    • Report page tooltips

    • Field parameters and dynamic dimensions

    • What-if parameters

    • Mobile layout and accessibility

    • Interactive executive dashboards

  6. Power BI Service & Deployment · 3h
    • Publishing reports and semantic models

    • Workspace creation and management

    • Workspace roles and permissions

    • Apps and audience management

    • Semantic model ownership

    • Scheduled refresh and refresh history

    • On-premises data gateway

    • Deployment pipelines

    • Development, Test and Production environments

    • Endorsement and certification overview

  7. Power BI Administration & Governance · 5h
    • Power BI tenant architecture

    • Power BI Admin Portal

    • Tenant settings and organizational controls

    • Workspace administration

    • User, group and access management

    • Microsoft Entra ID integration

    • Row-Level Security and Object-Level Security

    • Data source and gateway administration

    • Capacity and license management

    • Monitoring usage and audit logs

    • Power BI governance and deployment standards

    • Data protection and sensitivity labels

    • Troubleshooting refresh and access issues

  8. Performance Optimization & Monitoring · 2h
    • Performance Analyzer

    • DAX Studio overview

    • Model size and cardinality optimization

    • Query performance troubleshooting

    • Refresh performance and incremental refresh

    • Capacity monitoring overview

    • Common report performance problems

  9. End-to-End Business Case & Project · 3h
    • Import business data from multiple sources

    • Transform data using Power Query

    • Design a star schema

    • Develop DAX measures and KPIs

    • Build an interactive dashboard

    • Implement security

    • Publish to Power BI Service

    • Configure refresh and workspace access

    • Demonstrate administration and monitoring

You will be able to:
  • By the end of this training, participants should be able to:

  • Design and implement advanced Power BI data models.

  • Write intermediate and advanced DAX measures.

  • Build interactive dashboards and reports.

  • Optimize Power Query transformations and data models.

  • Connect Power BI to SQL Server, Excel, Snowflake and other data sources.

  • Implement Row-Level Security (RLS) and Object-Level Security (OLS).

  • Publish and manage reports in Power BI Service.

  • Configure workspaces, semantic models, gateways and refresh schedules.

  • Administer Power BI environments, monitor usage and manage access.

  • Understand deployment pipelines and Power BI governance.

₹16,220per participant, + GST
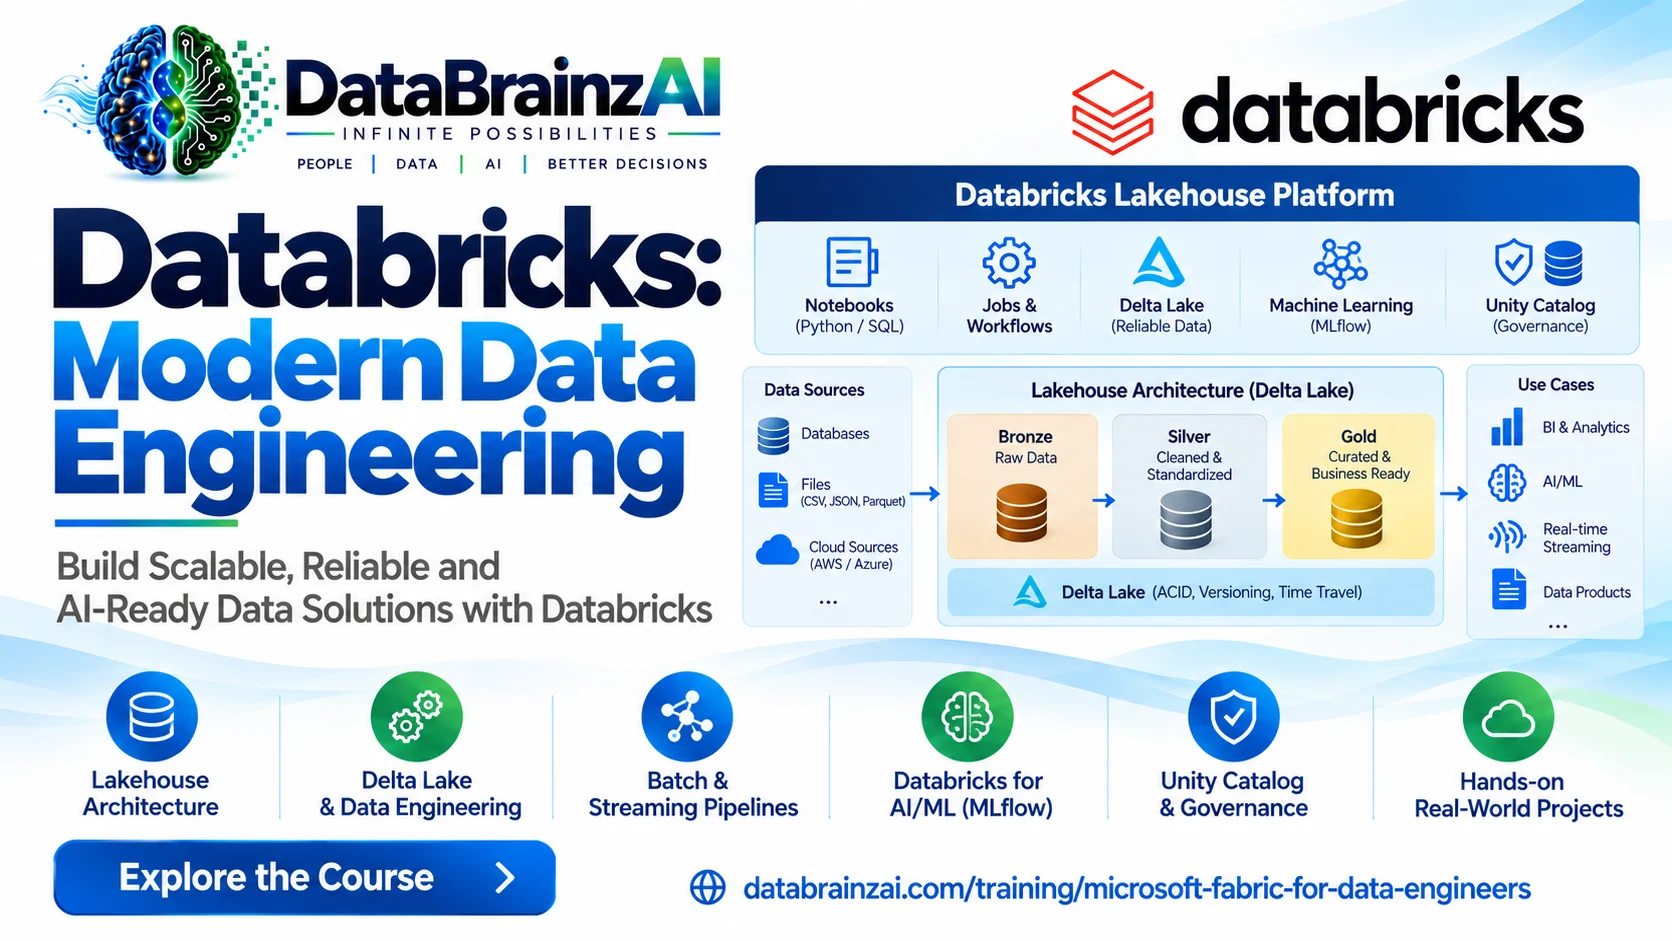
Databricks: Modern Data Engineering
Data EngineeringAdvanced

Databricks: Modern Data Engineering

modern data engineering with a comprehensive 3-month, hands-on Databricks program. Learn Apache Spark, PySpark, Delta Lake, Unity Catalog, Lakeflow and cloud lakehouse architecture. Master enterprise data modeling, including dimensional modeling and build production-oriented data pipelines.

Duration
60 hrs
Mode
Live online
Starts
3 Nov 2026
Syllabus · 21 modules · Mon to Fri, 7pm - 8pm
  1. Lakehouse Architecture and Databricks Platform · 2h

    OBJECTIVE:

    • Understand the lakehouse architecture and how Databricks brings together data engineering, analytics and AI.

    TOPICS:

    • evolution of data warehouses, data lakes and lakehouses

    • limitations of traditional two-tier architecture

    • lakehouse architecture and its characteristics

    • databricks data intelligence platform

    • control plane versus data plane

    • classic versus serverless compute

    • storage and compute separation

    • databricks on azure, aws and gcp

    • databricks workspace and account console

    • databricks Free Edition and workspace setup.

    PRACTICAL EXCERCISES:

    • explore a databricks workspace

    • create and execute a notebook

    • examine the lakehouse architecture using a sample dataset

    • create a basic delta table.

    ASSESSMENT:

    • explain the architecture and identify the role of each platform component.

  2. Workspace, Compute and Development Environment · 2h

    OBJECTIVE:

    • work with databricks development tools and configure appropriate compute resources.

    TOPICS:

    • workspace, notebooks and workspace files

    • python, SQL, scala and R notebook support

    • notebook magic commands and widgets

    • all-purpose versus job compute | serverless compute and SQL warehouses

    • databricks runtime and photon

    • cluster policies, autoscaling and auto-termination

    • access modes and libraries

    • databricks cli, rest api and sdk

    • databricks assistant and vs code extension.

    PRACTICAL EXCERCISES:

    • create notebooks using python and SQL

    • configure compute and explore runtime settings

    • use widgets and notebook parameters

    • run a notebook using different compute options.

    ASSESSMENT:

    • select compute configurations for different workloads.

  3. Apache Spark Architecture and Fundamentals · 2h

    OBJECTIVE:

    • Understand distributed data processing and Spark execution.

    TOPICS:

    • spark architecture: driver, executors, tasks, stages and jobs

    • RDDs, data frames and data sets

    • transformations and actions

    • lazy evaluation

    • narrow and wide transformations

    • shuffle operations

    • spark SQL and catalyst optimizer

    • adaptive query execution

    • spark ui and execution plans

    • spark connect.

    PRACTICAL EXERCICES:

    • create data frames from csv and json

    • apply transformations and actions

    • examine spark execution plans

    • analyze shuffles using spark UI.

    ASSESSMENT:

    • explain the execution flow of a Spark application.

  4. PySpark Programming · 4h

    OBJECTIVE:

    • Develop PySpark applications for data engineering workloads.

    TOPICS:

    • python programming for data engineering

    • data frame creation and schema definition

    • column expressions and built-in functions

    • filtering, sorting and aggregations

    • joins and window functions

    • null handling and data cleansing

    • user-defined functions and pandas UDFs

    • partitioning, repartition and coalesce

    • caching and persistence

    • error handling and reusable transformations.

    PRACTICAL EXERCICES:

    • build a PySpark ETL pipeline

    • cleanse customer and transaction data

    • perform joins and aggregations

    • develop reusable transformation functions

    ASSESSMENT:

    • develop a PySpark pipeline from a source dataset to a curated data frame.

  5. Databricks SQL and Data Analysis · 3h

    OBJECTIVE:

    • Use SQL to query, transform and analyze lakehouse data.

    TOPICS:

    • databricks SQL environment

    • SQL editor and query history

    • table and view creation

    • join, cte and window functions

    • advanced SQL functions

    • query plans and query profiles

    • SQL warehouses

    • AI/BI dashboards and genie overview

    • power bi connectivity.

    PRACTICAL EXERCICES:

    • develop analytical SQL queries

    • create views and reporting tables

    • build a simple dashboard

    • query delta tables using a SQL warehouse.

    ASSESSMENT:

    • create a reporting dataset and dashboard from transactional data.

  6. Data Modeling Fundamentals for Lakehouse · 2h

    OBJECTIVE:

    • Apply enterprise data modeling principles to a modern lakehouse.

    TOPICS:

    • conceptual, logical and physical data modeling

    • business processes and data requirements

    • entities, attributes, keys and relationships

    • normalization and denormalization

    • oltp versus analytical models

    • enterprise data domains

    • data modeling considerations for distributed storage

    • modeling standards and documentation

    • data architecture and modeling responsibilities.

    PRACTICAL EXERCICES:

    • analyze a banking or retail business case

    • develop a conceptual and logical data model

    • identify source-to-target mappings

    • map the model to the lakehouse layers.

    ASSESSMENT:

    • design a logical data model and explain its implementation in Databricks.

  7. Delta Lake and Lakehouse Storage · 2h

    OBJECTIVE:

    • Use Delta Lake to build reliable, versioned and performant data tables.

    TOPICS:

    • delta Lake architecture and transaction log

    • ACID transactions and optimistic concurrency

    • delta table creation and management

    • schema enforcement and schema evolution

    • merge, update and delete

    • time travel and restore

    • change data feed

    • managed and external tables

    • shallow and deep clones

    • deletion vectors and delta uniform

    • optimize, vacuum and liquid clustering.

    PRACTICAL EXERCICES:

    • create and modify Delta tables

    • implement incremental merge

    • recover historical data using time travel

    • examine delta transaction history and optimize a table.

    ASSESSMENT:

    • Implement an incremental Delta Lake solution with historical recovery.

  8. Medallion Architecture and Pipeline Design · 2h

    OBJECTIVE:

    • design and implement layered lakehouse pipelines.

    TOPICS:

    • bronze, silver and gold architecture

    • raw data retention and replayability

    • data cleansing and standardization

    • data quality rules and validation

    • conformed data and reusable transformations

    • business-ready aggregates and data marts

    • pipeline dependencies and data lineage

    • batch versus incremental processing

    • architecture and naming standards.

    PRACTICAL EXERCICES:

    • build a bronze-to-silver-to-gold pipeline

    • apply data quality rules

    • implement duplicate detection

    • develop a business-ready gold dataset.

    ASSESSMENT:

    • Design and implement a complete medallion pipeline.

  9. Dimensional Modeling on Databricks · 2h

    OBJECTIVE:

    • Design analytical data models and implement them in the lakehouse.

    TOPICS:

    • dimensional modeling principles

    • star and snowflake schemas

    • fact table grain and measures

    • transaction, periodic snapshot and accumulating snapshot facts

    • dimension design and surrogate keys

    • slowly changing dimensions: types 1, 2 and 3

    • role-playing and junk dimensions

    • bridge tables and many-to-many relationships

    • fact and dimension loading patterns

    • semantic modeling for BI.

    PRACTICAL EXERCICES:

    • design a banking or retail star schema

    • implement fact and dimension tables in Delta Lake

    • implement scd type 2 using SQL or PySpark

    • create a gold-layer dimensional model.

    ASSESSMENT:

    • build a dimensional model and demonstrate historical reporting.

  10. Data Ingestion and Incremental Processing · 2h

    OBJECTIVE:

    • build reliable ingestion pipelines from files, databases and event sources.

    TOPICS:

    • batch ingestion patterns

    • auto loader and cloudFiles

    • file notification and directory listing modes

    • schema inference and evolution

    • copy into

    • lakeflow connect overview

    • database ingestion and lakehouse federation

    • ingestion from kafka, azure event hubs and amazon kinesis

    • checkpointing and incremental processing

    • idempotency and recovery.

    PRACTICAL EXERCICES:

    • ingest csv, json and parquet files

    • implement auto loader

    • build an incremental file ingestion pipeline

    • apply schema evolution and handle corrupt records.

    ASSESSMENT:

    • Implement a restartable ingestion pipeline with audit information.

  11. Structured Streaming and Real-Time Data Processing · 2h

    OBJECTIVE:

    • Develop streaming pipelines for event-driven data processing.

    TOPICS:

    • structured Streaming architecture

    • streaming data frames and streaming sources

    • processing-time and available now triggers

    • checkpoints and fault tolerance

    • watermarks and late-arriving data

    • stateful aggregations and streaming joins

    • foreachBatch

    • deduplication and event-time processing

    • state store concepts

    • streaming pipeline monitoring.

    PRACTICAL EXERCICES:

    • process a simulated stream of financial transactions

    • implement event-time aggregations

    • handle late-arriving records

    • build a streaming-to-delta pipeline.

    ASSESSMENT:

    • Develop a streaming pipeline with checkpointing and late-data handling.

  12. Lakeflow Declarative Pipelines · 2h

    OBJECTIVE:

    • develop managed data pipelines using declarative programming.

    TOPICS:

    • lakeflow declarative pipelines architecture

    • streaming tables and materialized views

    • views and flows

    • expectations and data quality rules

    • auto cdc and apply changes

    • scd type 1 and type 2 implementation

    • triggered and continuous pipelines

    • development and production modes

    • pipeline event logs

    • incremental refresh and enzyme concepts.

    PRACTICAL EXERCICES:

    • create a declarative bronze-to-silver pipeline

    • apply expectations to reject or quarantine invalid records

    • implement scd type 2 using auto cdc

    • inspect pipeline execution and event logs.

    ASSESSMENT:

    • build a managed pipeline with data quality and cdc processing.

  13. Pipeline Orchestration with Lakeflow Jobs · 2h

    OBJECTIVE:

    • Orchestrate enterprise data pipelines with dependencies, scheduling and error handling.

    TOPICS:

    • jobs, tasks and DAGs

    • notebook, python, SQL and pipeline tasks

    • task dependencies and execution order

    • parameters and task values

    • for-each tasks and conditional execution

    • scheduling and file-arrival triggers

    • table-update triggers

    • retries, timeouts and notifications

    • repair runs and troubleshooting

    • multi-stage pipeline orchestration.

    PRACTICAL EXERCICES:

    • build a multi-task data engineering workflow

    • parameterize the pipeline

    • configure schedules

    • retries and failure notifications

    • implement a dependent bronze, silver and gold workflow.

    ASSESSMENT:

    • orchestrate an end-to-end pipeline and demonstrate failure recovery.

  14. Unity Catalog and Data Governance · 2h

    OBJECTIVE:

    • Implement enterprise data governance, access control and lineage.

    TOPICS:

    • unity catalog architecture

    • metastore, catalog, schema, table, view and volume

    • managed and external locations | storage credentials

    • privileges, ownership, grant and revoke

    • row filters and column masks

    • tags and attribute-based access control

    • data lineage and audit

    • system tables and catalog Explorer

    • workspace-catalog binding

    • data classification and governance policies.

    PRACTICAL EXERCICES:

    • create catalogs, schemas and volumes

    • implement role-based access

    • apply row filters and column masks

    • explore lineage and audit information.

    ASSESSMENT:

    • Implement a governed data access model for a business domain.

  15. Data Sharing, SQL Analytics and BI Integration · 2h

    OBJECTIVE:

    • deliver governed lakehouse data to analysts and external consumers.

    TOPICS:

    • databricks SQL warehouses

    • SQL query history and query profiles

    • AI/BI dashboards | AI/BI genie

    • SQL alerts and materialized views

    • unity catalog metric views

    • Power BI and Tableau integration

    • delta sharing

    • databricks marketplace and clean rooms overview

    • secure data sharing patterns.

    PRACTICAL EXERCICES:

    • create a Gold-layer analytics dataset

    • build an AI/BI dashboard

    • connect Power BI to a SQL warehouse

    • configure a demonstration of governed data sharing.

    ASSESSMENT:

    • build and present a business dashboard using governed data.

  16. Spark and Delta Lake Performance Optimization · 2h

    OBJECTIVE:

    • Diagnose and improve performance of large-scale data pipelines.

    TOPICS:

    • spark execution plans and query profiles

    • catalyst optimizer and AQE

    • partitioning versus liquid clustering

    • data skipping and statistics

    • broadcast joins and join strategies

    • skew handling and salting

    • repartition and coalesce

    • caching and persistence

    • small files and file sizing

    • predicate pushdown

    • spill, memory and shuffle optimization

    • optimize and predictive optimization.

    PRACTICAL EXERCICES:

    • analyze a slow Spark job

    • identify shuffles and data skew

    • optimize joins and table layout

    • compare query execution before and after tuning.

    ASSESSMENT:

    • Submit a performance tuning report with measured improvements.

  17. Security, Administration and Cost Management · 2h

    OBJECTIVE:

    • operate databricks workloads securely and efficiently.

    TOPICS:

    • users, groups and service principals

    • identity federation and SCIM

    • OAuth and personal access tokens

    • secrets and secret scopes

    • network security and private connectivity

    • encryption and customer-managed keys

    • cluster policies and access controls

    • system billing tables and usage dashboards

    • budgets, tags and cost allocation

    • job and query observability

    • monitoring data quality and drift.

    PRACTICAL EXERCICES:

    • configure secure access for a service principal

    • explore job and compute usage

    • build a simple cost monitoring report

    • investigate failed jobs and data quality alerts.

    ASSESSMENT:

    • review a platform configuration for security and cost controls.

  18. Databricks DevOps and CI/CD · 2h

    OBJECTIVE:

    • implement repeatable development and deployment practices for databricks projects.

    TOPICS:

    • git folders and version control

    • development, test and production environments

    • databricks asset bundles

    • bundle configuration and deployment targets

    • CI/CD with GitHub actions or azure DevOps

    • service principals for automated deployment

    • databricks cli

    • rest api and sdk

    • terraform provider overview

    • unit testing with pytest and chispa.

    PRACTICAL EXERCICES:

    • create a git-based databricks project

    • package a job using asset bundles

    • configure deployment targets

    • implement basic automated tests and deployment.

    ASSESSMENT:

    • deploy a sample pipeline through a controlled CI/CD workflow.

  19. Production Operations and Troubleshooting · 2h

    OBJECTIVE:

    • Maintain reliable and observable Databricks data pipelines.

    TOPICS:

    • Job and pipeline monitoring.

    • Spark UI and execution diagnostics.

    • Pipeline event logs.

    • Data quality monitoring and anomaly detection.

    • Retry, repair and recovery strategies.

    • Idempotent processing.

    • Logging and alerting.

    • Incident analysis and root-cause investigation.

    • Deployment rollback and recovery.

    • Production readiness checklists.

    PRACTICAL EXERCICES:

    • Troubleshoot failed pipeline runs.

    • Implement recovery and restart mechanisms.

    • Diagnose data quality failures.

    • Create an operational runbook.

    ASSESSMENT:

    • Complete a production incident simulation.

  20. Machine Learning and AI on Databricks — Introduction · 2h

    OBJECTIVE:

    • understand how the lakehouse supports data science and AI workloads.

    TOPICS:

    • MLflow experiment tracking

    • model registry in unity catalog

    • feature engineering and feature store

    • autoML overview

    • model serving

    • vector search

    • mosaic AI and agent development overview

    • data engineering responsibilities in ML pipelines

    • governance and monitoring of ML assets.

    PRACTICAL EXERCICES:

    • track a simple ML experiment

    • register a demonstration model

    • prepare a feature dataset from curated data

    • explore model serving and vector search.

    ASSESSMENT:

    • explain the integration of data engineering and a basic ML workflow.

  21. End-to-End Enterprise Lakehouse Implementation · 3h

    OBJECTIVE:

    • build an integrated enterprise data engineering solution using databricks.

    CASE STUDY:

    • Global Banking and Financial Services Lakehouse.

    BUSINESS SCENARIO:

    • A financial services organization receives customer, account, transaction and investment data from multiple source systems. It requires a modern lakehouse for operational reporting, historical analysis and advanced analytics.

    PROJECT ACTIVITIES:

    • ingest source files

    • implement bronze, silver and gold layers

    • build incremental pipelines using PySpark and delta lake

    • apply data quality rules and handle cdc

    • orchestrate pipelines using lakeflow jobs

    • configure unity catalog

    • optimize delta tables and spark workloads

    • implement deployment and monitoring practices.

    DELIVERABLES:

    • enterprise architecture diagram

    • conceptual and logical data models

    • PySpark notebooks and Delta tables

    • automated pipeline and orchestration

    • deployment and operational documentation.

You will be able to:
  • explain databricks lakehouse architecture and its core components.

  • databricks workspaces, compute resources, notebooks and SQL warehouses.

  • develop PySpark programs for large-scale data processing.

  • create, modify and optimize delta tables.

  • batch and incremental data ingestion using Auto Loader and other techniques.

  • build bronze, silver and gold pipelines using databricks.

  • develop data pipelines using lakeflow declarative pipelines and lakeflow jobs.

  • implement data quality, governance and security using unity catalog.

  • apply spark and delta lake performance optimization techniques.

  • deploy and manage data pipelines using git and databricks asset bundles.

  • monitor pipeline execution, troubleshoot failures and control compute costs.

  • build a complete enterprise lakehouse project with architecture and data models.

₹19,493₹25,990per participant, + GST
Early Bird Offer · 25% off · till 14 Nov 2026Code: EARLY25
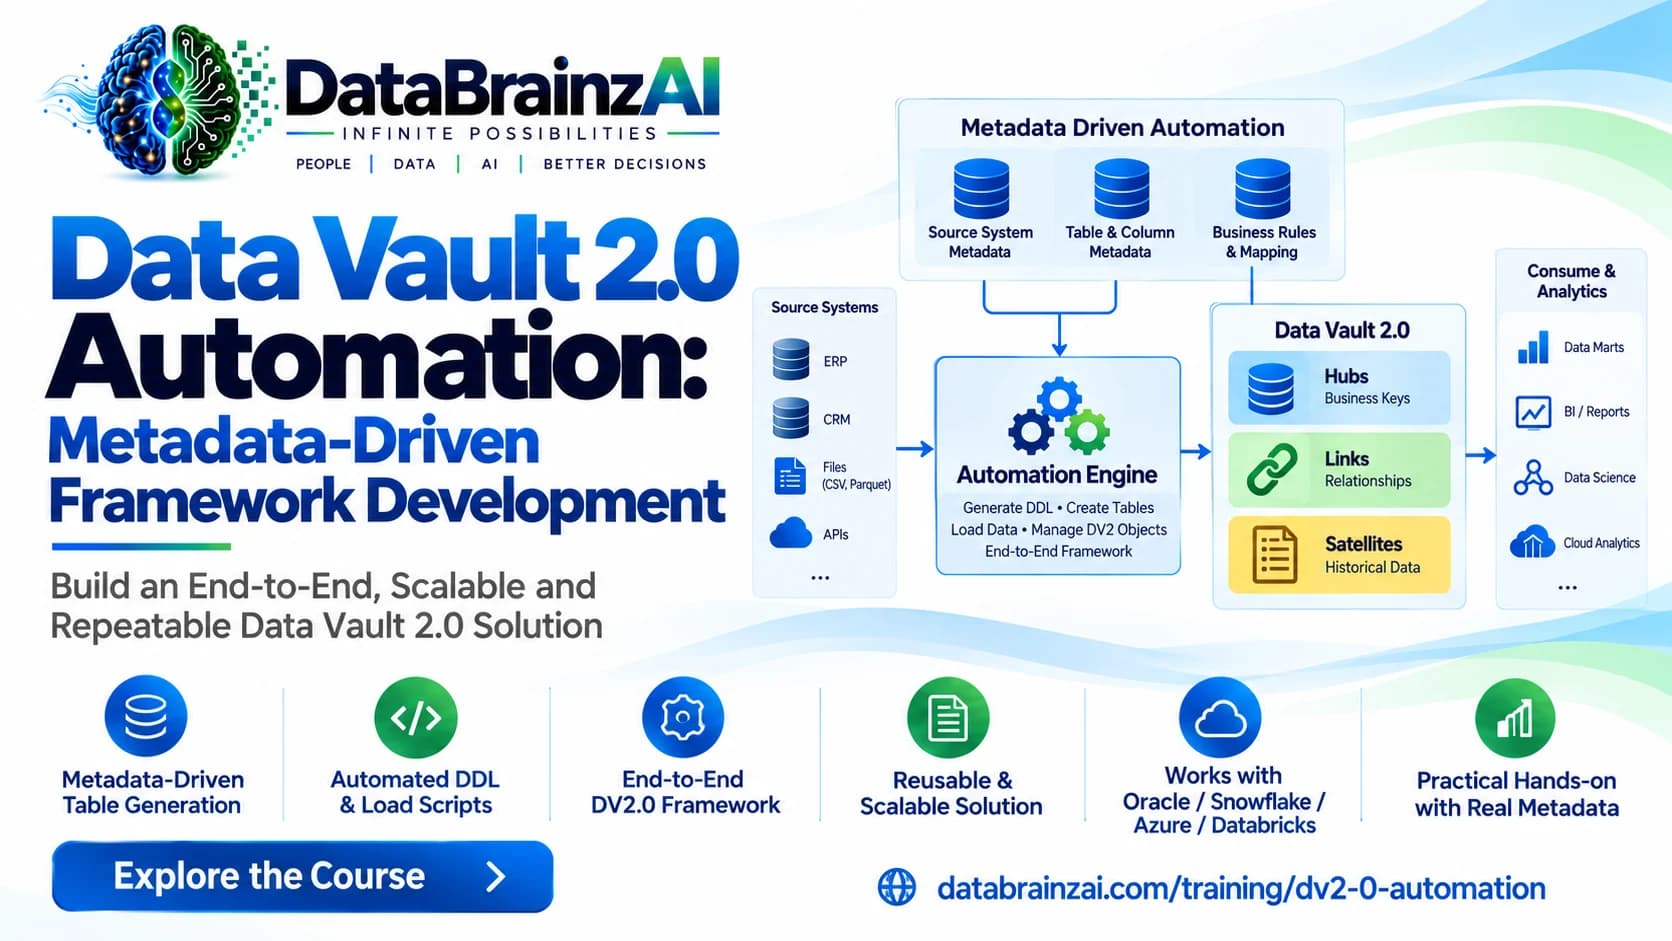
Data Vault 2.0 Automation: Metadata-Driven Framework Development
Data Vault 2.0Advanced

Data Vault 2.0 Automation: Metadata-Driven Framework Development

Build an end-to-end, metadata-driven Data Vault 2.0 automation framework using Snowflake SQL and Python. Automate data vault tables, metadata management, source ingestion, Hash Key & HashDiff generation, and ETL execution. Develop a reusable automation framework through practical exercises.

Duration
30 hrs
Mode
Live online
Starts
30 Oct 2026
Syllabus · 15 modules
  1. Data Vault 2.0 Automation Architecture · 2h

    Objective:

    • understand the architecture and components of a metadata-driven automation framework.

    Topics:

    • data vault 2.0 implementation lifecycle

    • manual versus automated data vault development

    • metadata-driven architecture and design principles

    • automation framework components

    • source, landing, bronze, raw vault and business vault layers

    • SQL and python responsibilities

    • framework configuration and execution flow.

    Practical Excercises:

    • design an end-to-end automation architecture and define its components.

    Deliverable:

    • automation architecture diagram.

  2. Metadata Repository Design · 2h

    OBJECTIVE:

    • design metadata structures that drive automated data vault development.

    TOPICS:

    • metadata repository architecture

    • source system and source object metadata

    • file format and stage metadata

    • table and column metadata

    • hub, link and satellite configuration

    • business key and hashdiff metadata

    • load configuration and execution status

    • metadata naming standards and relationships

    PRACTICAL EXCERCISES:

    • create metadata tables such as:

    • GTE_METADATA_SOURCE_SYSTEM

    • GTE_METADATA_FILE_FORMAT

    • GTE_METADATA_STAGE_LOAD

    • metadata tables for columns, hubs, links and satellites.

    DELIVERABLE:

    • metadata repository with sample configurations.

  3. Metadata Extraction and Management · 2h

    OBJECTIVE:

    • extract database metadata and populate the automation repository.

    TOPICS:

    • database catalog and information schema

    • extracting tables, columns and data types

    • primary key and foreign key metadata

    • metadata validation and synchronization

    • source-to-target metadata mapping

    • dynamic SQL generation from metadata

    • metadata-driven configuration management

    PRACTICAL EXCERCISES:

    • develop SQL scripts to extract source table and column metadata and populate the repository.

    DELIVERABLE:

    • automated metadata extraction scripts.

  4. Python Automation Framework · 2h

    OBJECTIVE:

    • develop a reusable python framework for executing metadata-driven automation.

    TOPICS:

    • python project structure and modular design

    • snowflake python connector

    • connection management and environment variables

    • reading metadata from snowflake

    • executing SQL dynamically

    • parameterized scripts and reusable functions

    • logging, configuration and exception handling

    • master execution program.

    PRACTICAL EXCERCISES:

    • develop python modules for connecting to snowflake, retrieving metadata and executing SQL scripts.

    DELIVERABLE:

    • reusable python execution framework.

  5. Automated File Ingestion and Landing Layer · 2h

    OBJECTIVE:

    • automate source file ingestion and landing table creation.

    TOPICS:

    • snowflake internal and external stages

    • automated file format creation

    • CSV, JSON and Parquet file handling

    • stage creation using metadata

    • file discovery and validation

    • LIST, PUT and COPY INTO

    • file patterns and incremental file processing

    • landing table generation and load auditing.

    PRACTICAL EXCERCISES:

    • develop python and SQL scripts to create stages, file formats and landing tables, then load source files.

    DELIVERABLE:

    • metadata-driven file ingestion framework.

  6. Automated Bronze Layer Generation · 2h

    OBJECTIVE:

    • automate bronze table creation and ingestion using source metadata.

    TOPICS:

    • bronze layer architecture and design | source-to-bronze mapping

    • automated table DDL generation

    • dynamic column and data type mapping

    • audit and technical columns

    • source system identifiers

    • file name, load timestamp and record tracking

    • bronze layer validation and reconciliation.

    PRACTICAL EXCERCISES:

    • build a python generator that reads metadata and creates bronze tables and corresponding load scripts.

    DELIVERABLE:

    • reusable bronze table generator.

  7. Automated Hub Generation · 2h

    OBJECTIVE:

    • generate hub tables and loading logic automatically from metadata.

    TOPICS:

    • hub metadata requirements | business key identification and configuration

    • hash key generation

    • hub DDL generation

    • record source and load timestamp

    • dynamic SQL for hub loading

    • duplicate detection and insert-only loading

    • multi-source hub integration.

    PRACTICAL EXCERCISES:

    • build a metadata-driven hub generator and load customer and account hubs.

    DELIVERABLE:

    • hub DDL and load automation modules.

  8. Automated Link Generation · 2h

    OBJECTIVE:

    • automate link table creation and loading using relationship metadata.

    TOPICS:

    • link metadata design

    • hub relationship configuration

    • link Hash Key generation

    • foreign key resolution

    • standard and dependent-child Links

    • dynamic link DDL generation

    • link loading and duplicate prevention

    • handling missing Hub records.

    PRACTICAL EXCERCISES:

    • develop a link generator for customer-account and account-transaction relationships.

    DELIVERABLE:

    • automated link generation and loading scripts.

  9. Automated Satellite Generation · 2h

    OBJECTIVE:

    • automate satellite DDL and loading logic for historical data management.

    TOPICS:

    • satellite metadata and attribute configuration

    • hub, link and satellite generation

    • hashdiff generation

    • satellite DDL generation

    • change detection and incremental loading

    • insert-only historization

    • handling nulls and changed attributes

    • multi-source and source-aligned satellites.

    PRACTICAL EXCERCISES:

    • build a satellite generator and automate customer profile and account status loading.

    DELIVERABLE:

    • reusable satellite generator and load framework.

  10. Automated Raw Vault Loading · 2h

    OBJECTIVE:

    • integrate hub, link and satellite loading into a configurable raw vault pipeline.

    TOPICS:

    • raw vault load sequence

    • metadata-driven dependency management

    • hub, link and satellite execution order

    • incremental loading and change detection

    • late-arriving records

    • transaction handling and restartability

    • load reconciliation and record counts

    • load status and audit management.

    PRACTICAL EXCERCISES:

    • build an automated Raw Vault loader that executes the generated scripts in the correct order.

    DELIVERABLE:

    • end-to-end raw vault loading engine.

  11. Business Vault Automation · 2h

    OBJECTIVE:

    • extend the automation framework to support derived structures and business rules.

    TOPICS:

    • business vault metadata requirements

    • derived satellite generation

    • business rule configuration

    • calculated attributes and transformations

    • effectivity processing

    • business key resolution

    • automated business vault DDL generation

    • dependency management for derived objects.

    PRACTICAL EXCERCISES:

    • Configure and generate a derived Satellite for customer classification using business rules.

    DELIVERABLE:

    • Business Vault automation design and sample scripts.

  12. PIT and Bridge Table Automation · 2h

    OBJECTIVE:

    • automate the generation and maintenance of PIT and bridge structures.

    TOPICS:

    • PIT and bridge metadata

    • PIT table DDL generation

    • satellite dependency configuration

    • snapshot and incremental PIT loading

    • bridge relationship metadata

    • bridge table generation and refresh

    • historical point-in-time retrieval

    • performance and maintenance considerations.

    PRACTICAL EXCERCISES:

    • Generate a customer PIT and a customer-account Bridge from metadata.

    DELIVERABLE:

    • PIT and bridge automation modules.

  13. Metadata-Driven Orchestration · 2h

    OBJECTIVE:

    • build a centralized execution engine to control the complete automation pipeline.

    TOPICS:

    • master execution framework

    • configuration-driven processing

    • pipeline dependency management

    • sequential and parallel execution

    • task status and execution logs

    • retry and restart mechanisms

    • failure handling and notifications

    • integration with scheduling tools.

    PRACTICAL EXCERCISES:

    • develop a master python program that executes ingestion, bronze generation, raw vault loading

    • downstream processing based on metadata.

    DELIVERABLE:

    • centralized orchestration framework.

  14. Automation Testing, Auditing and Optimization · 2h

    OBJECTIVE:

    • implement quality controls and operational capabilities for the automation framework.

    TOPICS:

    • metadata validation

    • generated SQL validation

    • data quality and reconciliation

    • duplicate and missing record checks

    • exception and error logging

    • audit tables and execution history

    • performance optimization

    • secure configuration and credentials

    • unit and integration testing.

    PRACTICAL EXCERCISES:

    • introduce error handling, audit logging and validation into the existing automation framework.

    DELIVERABLE:

    • tested automation components and operational monitoring design.

  15. End-to-End Data Vault Automation Project · 2h

    OBJECTIVE:

    • Integrate course modules into a working metadata-driven data vault automation solution

    BUSINESS SCENARIO:

    • a financial organization receives customer, account, order, trade and portfolio data from multiple source systems.

    • objective is to automate ingestion, bronze creation and data vault loading through a centralized metadata.

    PROJECT ACTIVITIES:

    1. configure file metadata

    2. extract table and column metadata

    3. generate stages, file formats and landing tables

    4. generate bronze tables and ingestion scripts

    5. generate hub, link and satellite DDL

    6. automate hash key and hashdiff generation

    7. execute raw vault loading

    8. implement audit logging and error handling

    9. configure master execution program

    10. run the complete pipeline and validate the results.

    FINAL DELIVERABLES:

    • metadata repository

    • python automation framework

    • automated DDL generators

    • hub, link and satellite loaders

    • master execution program

    • audit and validation scripts

You will be able to:
  • Design a metadata-driven Data Vault 2.0 automation architecture.

  • Create metadata tables to store source, file, object and loading configurations.

  • Automate source metadata extraction and landing table generation.

  • Develop reusable SQL and Python scripts to generate Data Vault database objects.

  • Automate Hub, Link and Satellite DDL generation.

  • Generate Hash Keys and HashDiffs using standardized metadata-driven rules.

  • Automate data ingestion and Raw Vault loading.

  • Implement incremental processing, historization and duplicate detection.

  • Build a metadata-driven execution engine for managing pipeline dependencies.

  • Implement audit logging, exception handling and restartability.

  • Integrate individual automation components into an end-to-end framework.

  • Extend the framework to support additional source systems and business domains.

₹29,985per participant, + GST